Which Cheap AI Image Model Gets the Text Right? 4 Models Tested
Nano Banana 2.1 printed every word exactly right on 6 of 6 text prompts, at $0.036 per correct image. GPT Image 1 mini and Gemini 3.1 Flash Lite got 5 of 6, at $0.025 and $0.040. FLUX.2 klein 4B got 0 of 6: six renders, $0.102, no correct image. Which model fits depends on the kind of text. These are four cheap OpenRouter models, not the whole market; the 2026 roundup is a separate list.
Tested on 2026-11-18 with google/gemini-3.1-flash-lite-image, google/gemini-nano-banana-2.1, black-forest-labs/flux.2-klein-4b and openai/gpt-image-1-mini through OpenRouter.
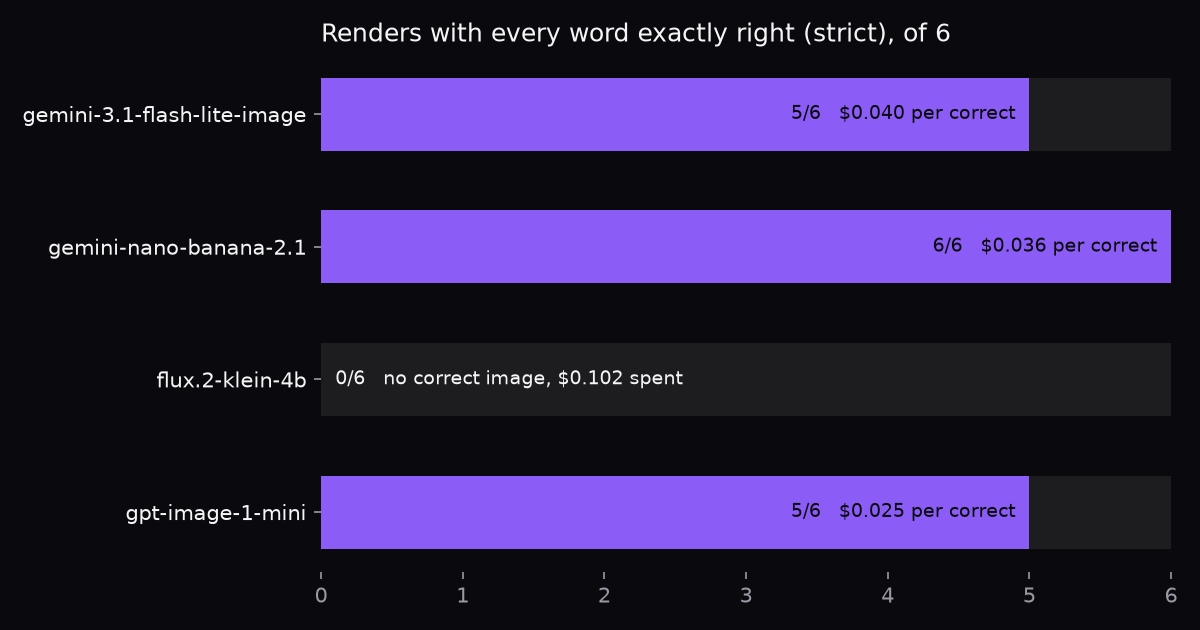
Purple is the count of renders with every word right (strict). Grey is the rest of the 6. Cost per correct image is in the tables below.
What did each model get right?
Yes means every requested word and number was exactly right and nothing else was written in the image (strict). Lenient scoring allows one wrong character in the image.
| Text type | Flash Lite | Nano Banana | FLUX klein | GPT mini |
|---|---|---|---|---|
| Short sign | yes | yes | no | yes |
| Two-line label | yes | yes | no | yes |
| Price list | yes | yes | no | yes |
| Diagram, 4 labels | yes | yes | no | no |
| UI mock-up | no | yes | no | yes |
| Slovak line | yes | yes | no | yes |
Three calls were made at scoring time, after the renders existed:
- Capitals are not scored. It affects only P6, where Flash Lite and GPT mini used capitals.
- Line breaks and spacing are not scored. It affects GPT mini on P2 (BLUEBERRY and JAM on separate lines) and P3 ("Juice3.50").
- Extra writing the prompt forbade fails both scores. It rejects Flash Lite on P5.
With those calls, lenient scoring gave the same result on all 24 renders. There is no overall winner in the table. Nano Banana is the only model right on both the diagram and the UI mock-up. FLUX klein is right on none.
What did we ask for?
Six prompts a builder or marketer would give an image API when the picture must carry words. Each names the exact text and says nothing else may be written. One render per prompt per model, 1:1, and no second render when the first one came back.
| ID | Use | Prompt, verbatim |
|---|---|---|
| P1 | Short sign | A plain wooden road sign on a grassy verge with the exact words "FRESH EGGS" painted in large black capital letters, nothing else written anywhere in the image. |
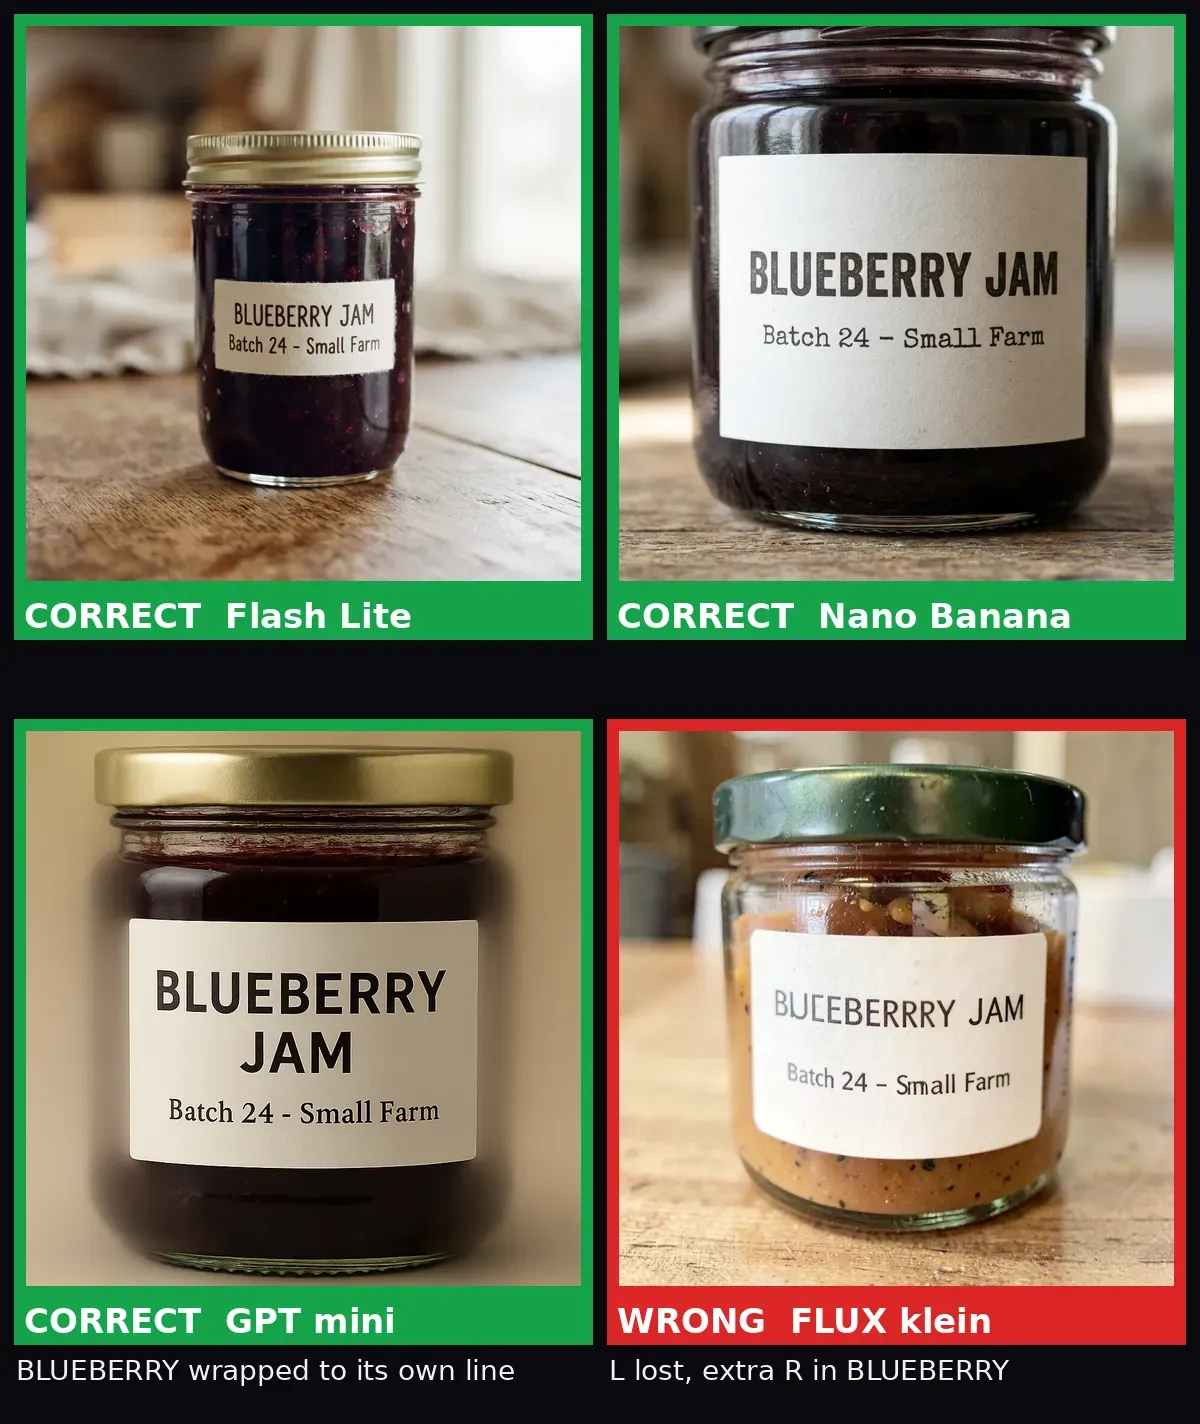
| P2 | Two-line label | A small product label on a glass jar with exactly two lines of text: first line "BLUEBERRY JAM", second line "Batch 24 - Small Farm". Nothing else written anywhere in the image. |
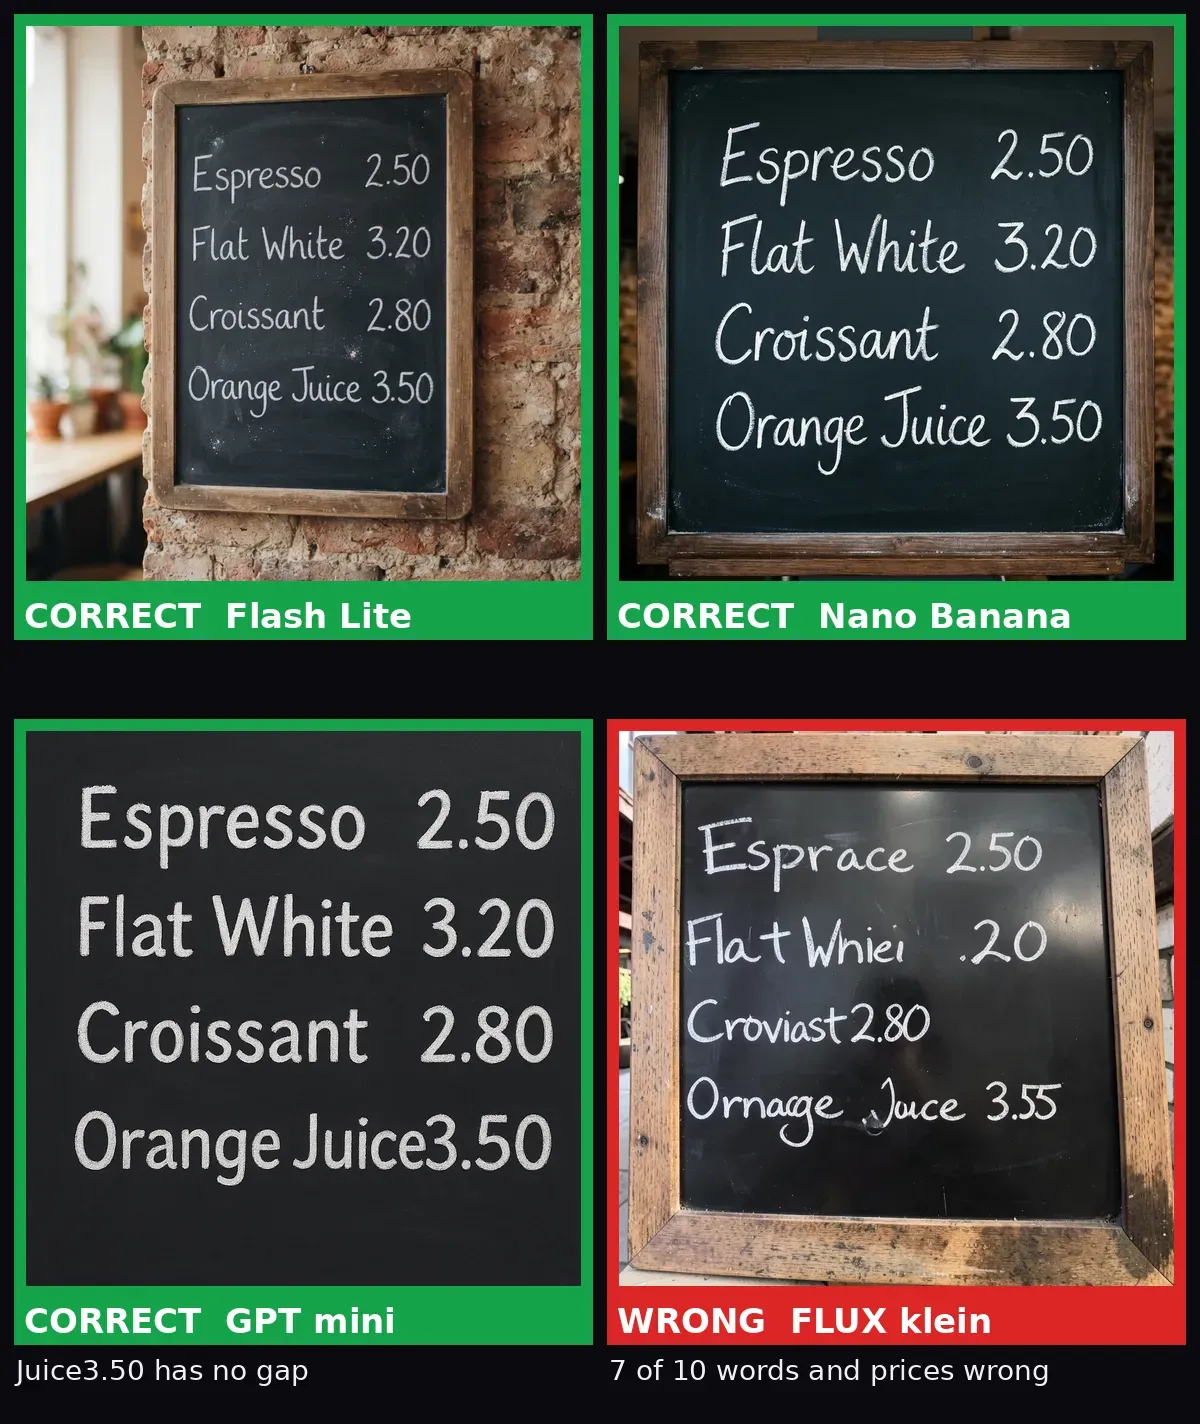
| P3 | Price list | A cafe chalkboard price list with exactly these four lines: "Espresso 2.50", "Flat White 3.20", "Croissant 2.80", "Orange Juice 3.50". Nothing else written anywhere in the image. |
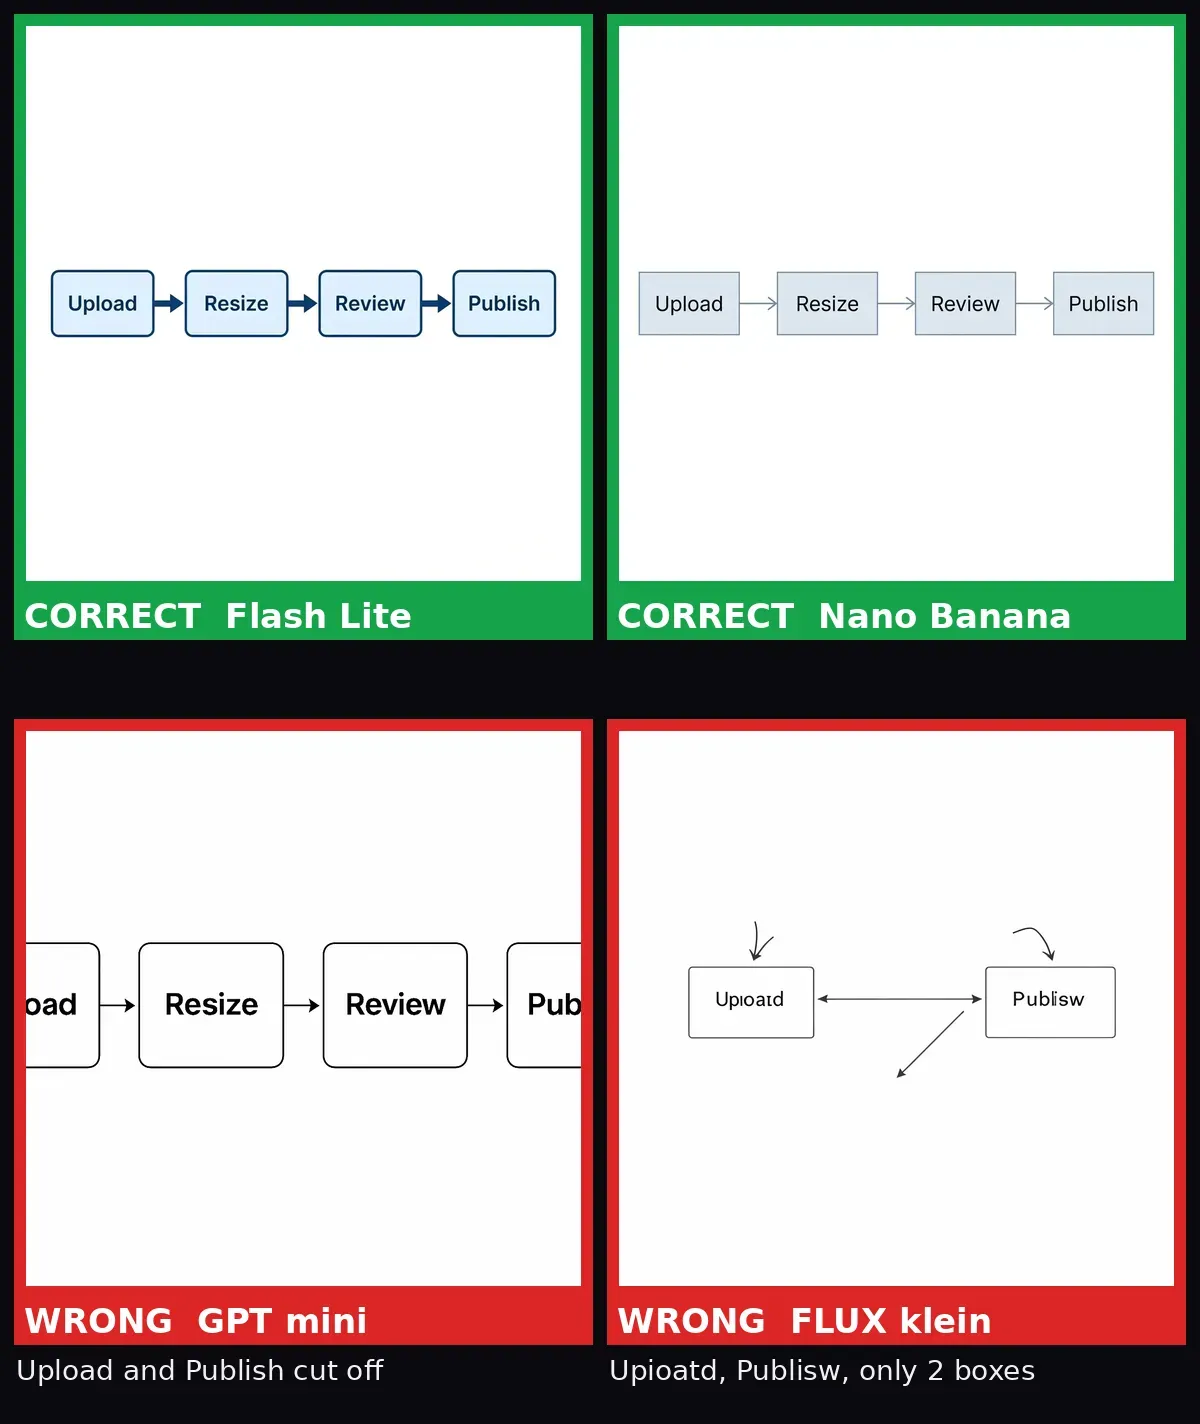
| P4 | Diagram, 4 labels | A clean flat diagram on a white background: four boxes connected by arrows in a row, labelled exactly "Upload", "Resize", "Review", "Publish". Nothing else written anywhere in the image. |
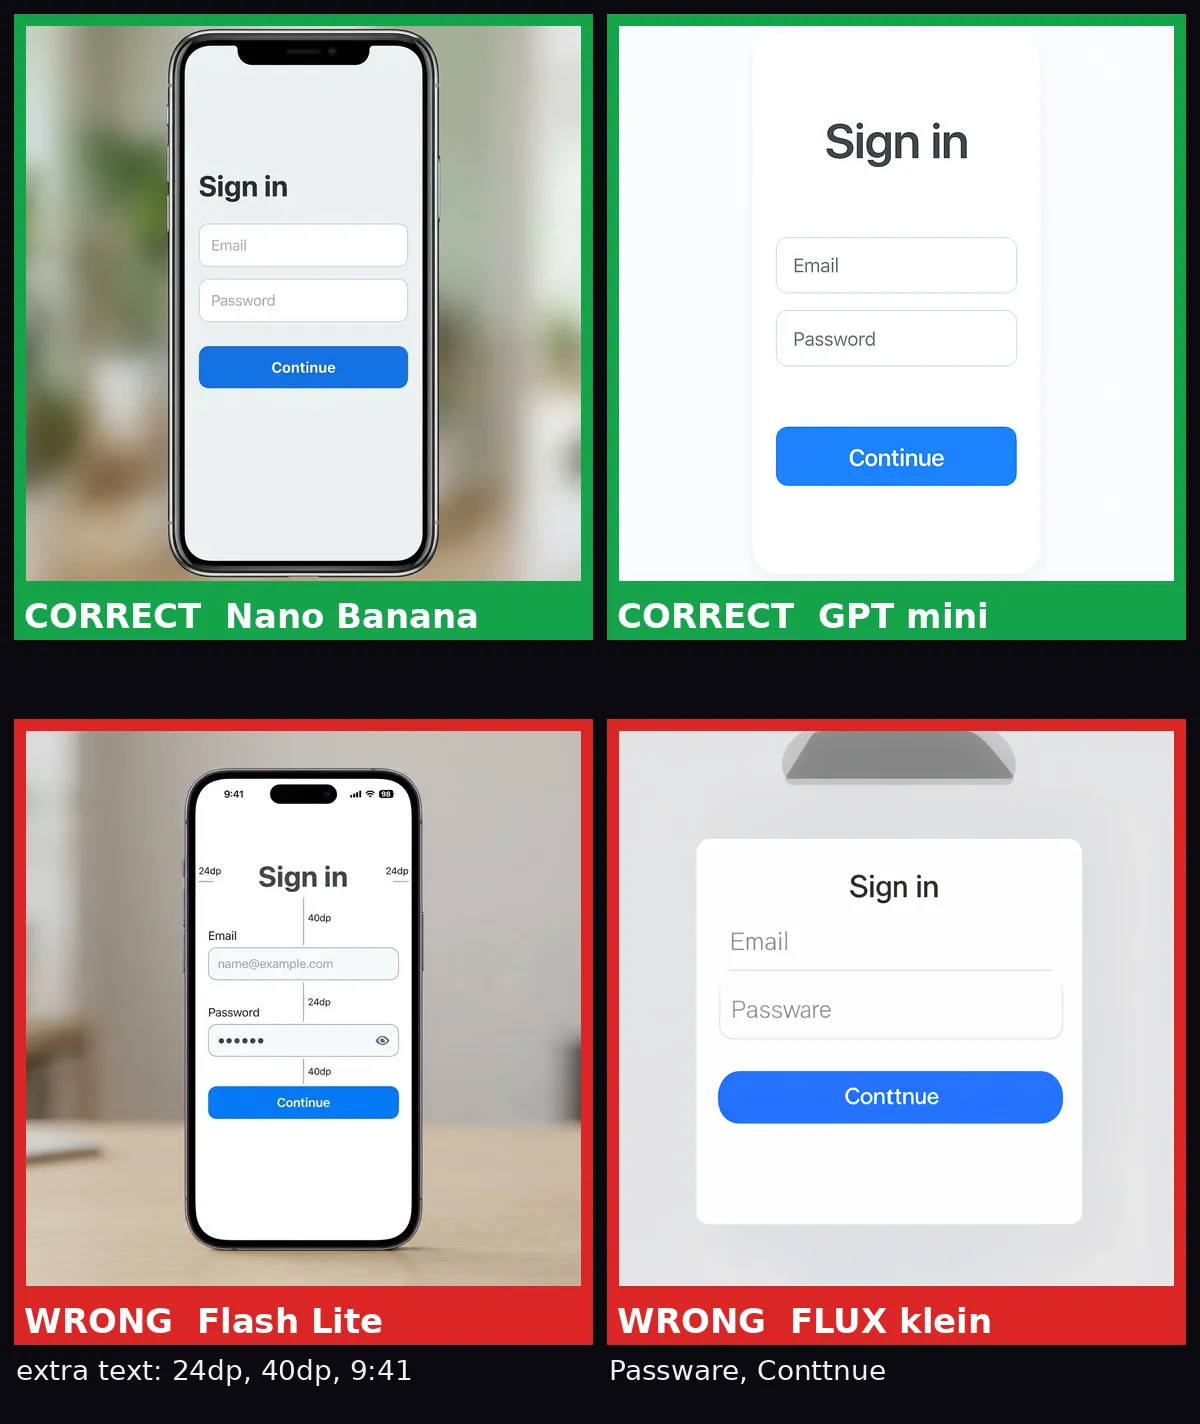
| P5 | UI mock-up | A mobile app login screen mock-up: a title reading "Sign in", two input fields labelled "Email" and "Password", and a blue button reading "Continue". Nothing else written anywhere in the image. |
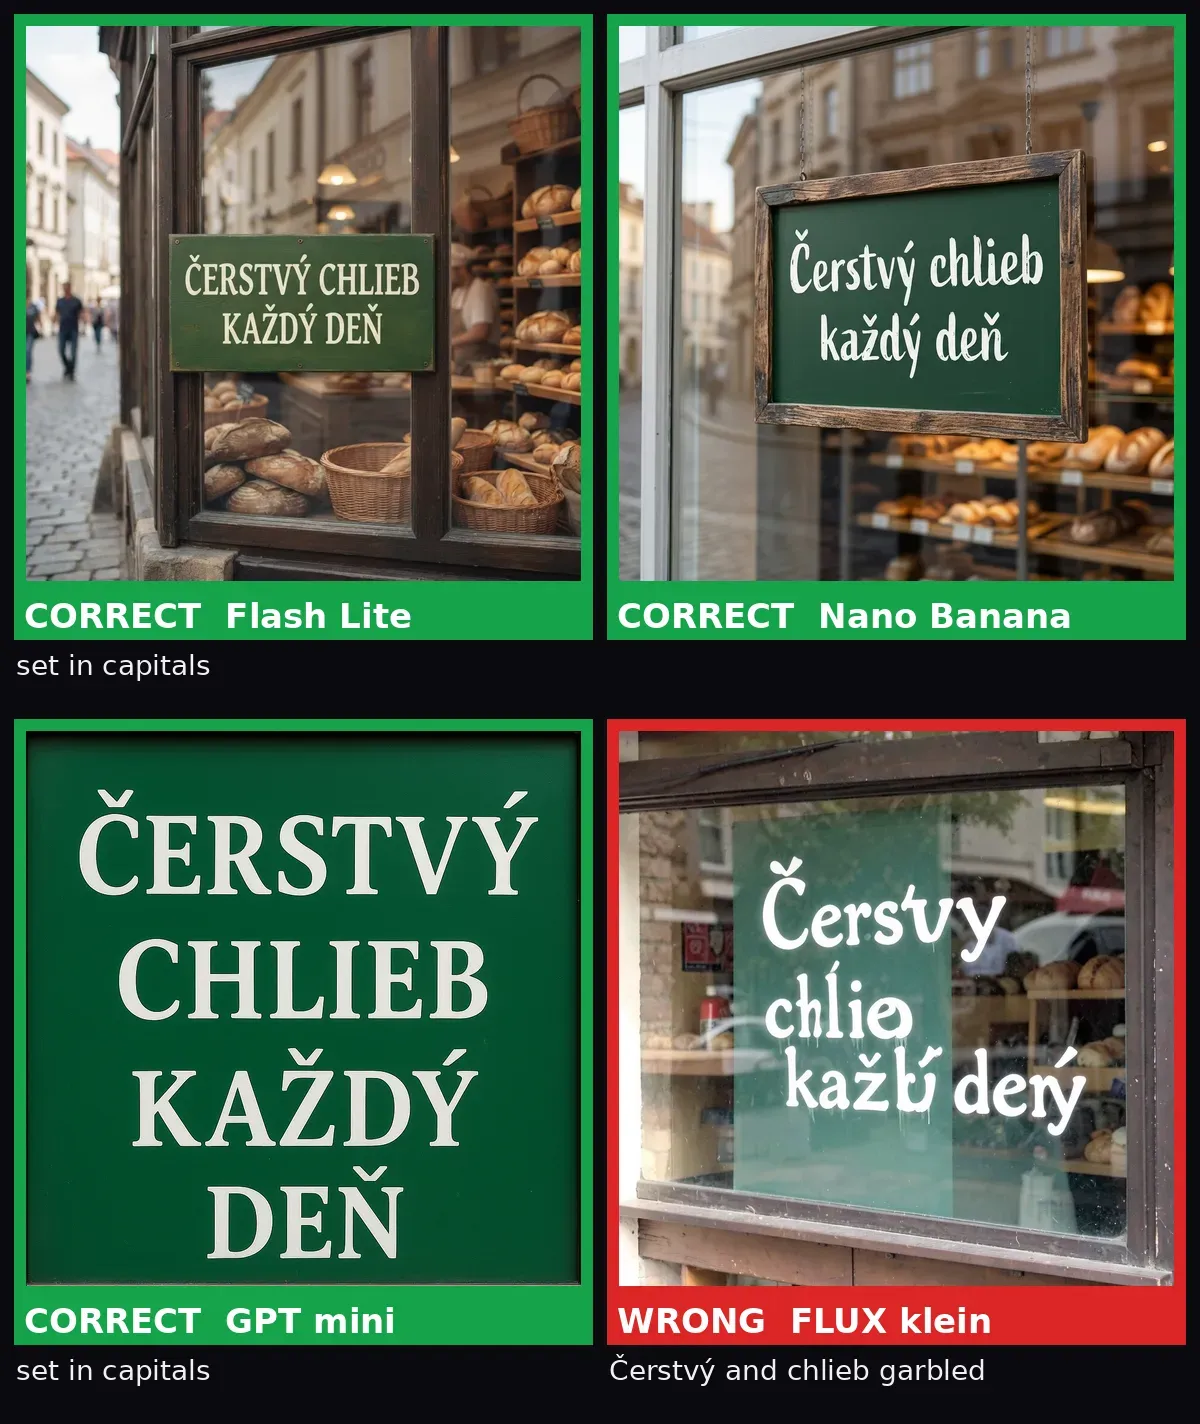
| P6 | Slovak line | A bakery shop window sign with the exact Slovak words "Čerstvý chlieb každý deň" in white letters on a green board, nothing else written anywhere in the image. |
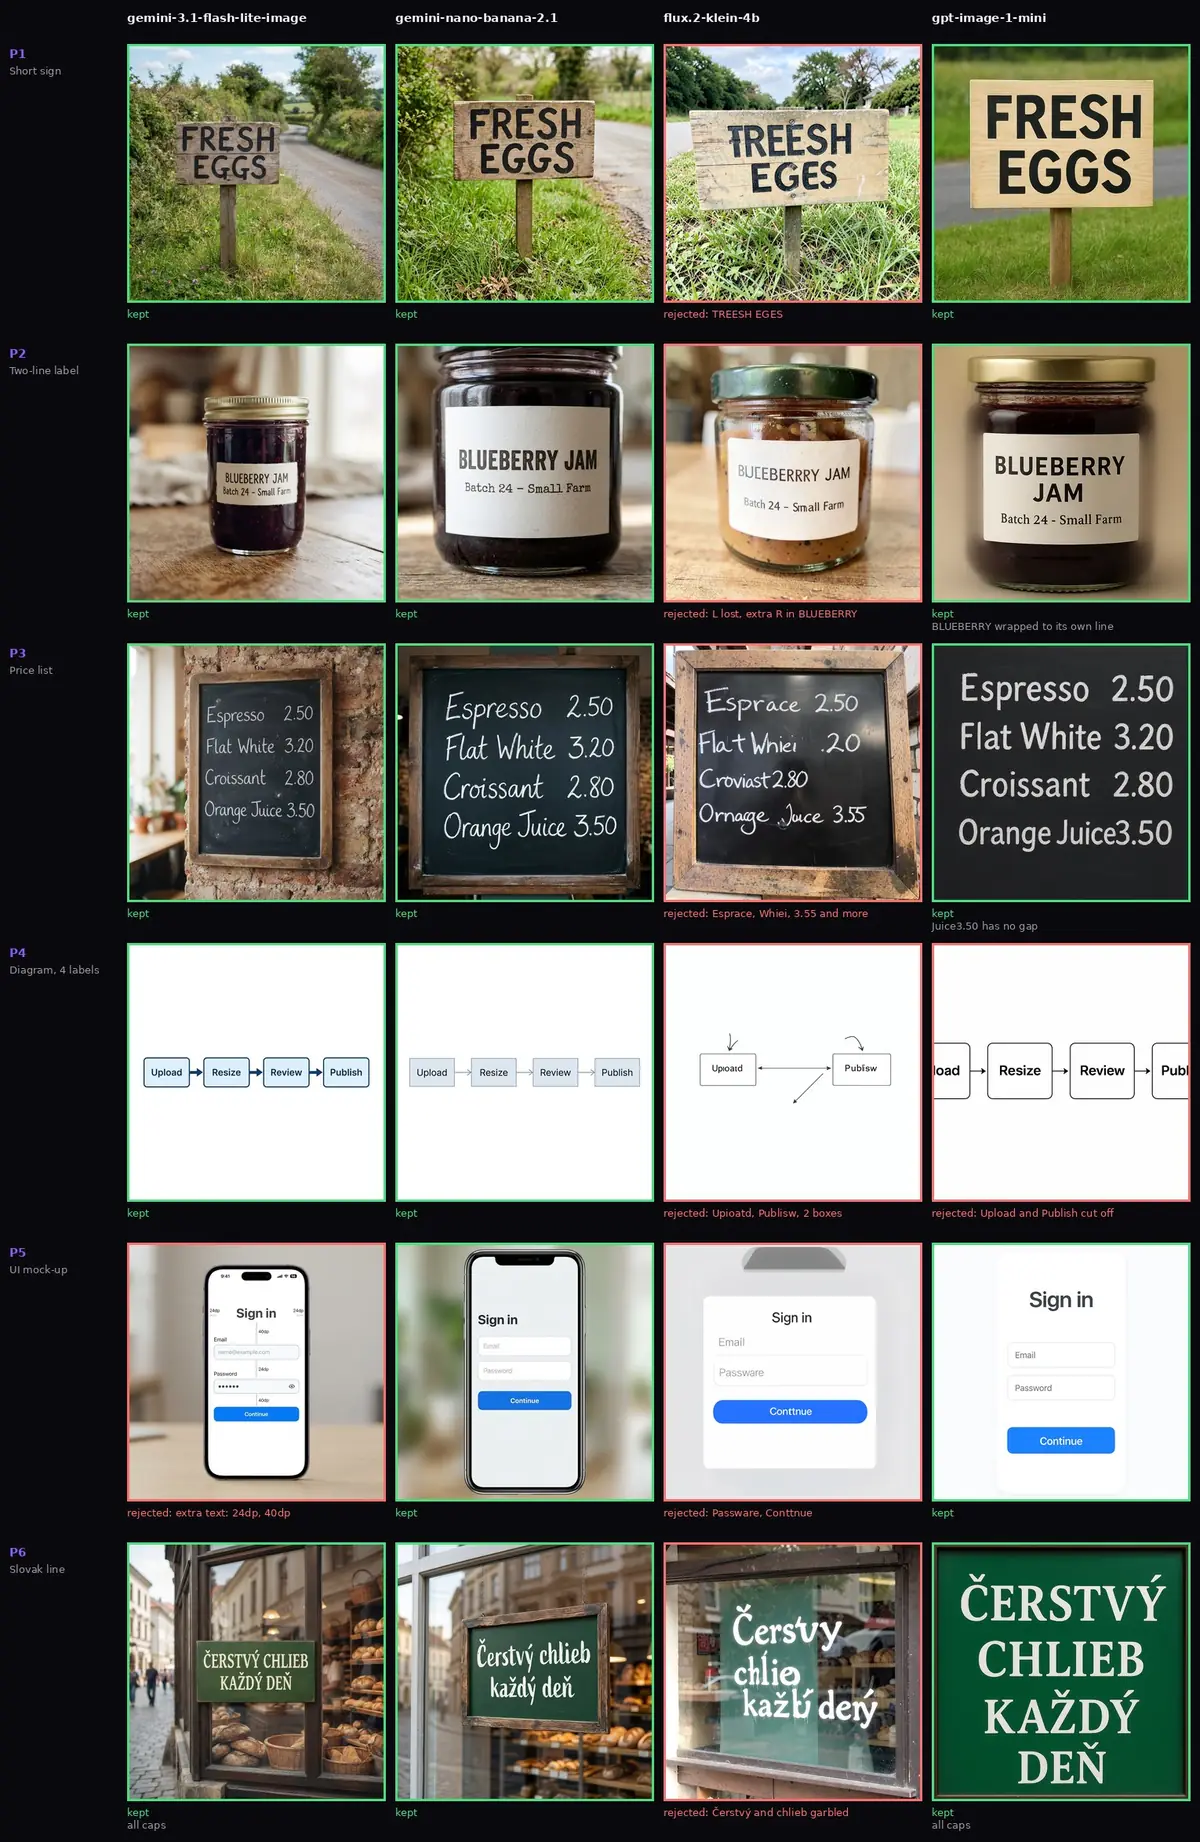
Every render, no selection. Green: kept (strict). Red: rejected, with the reason.
Which model gets a short sign right?
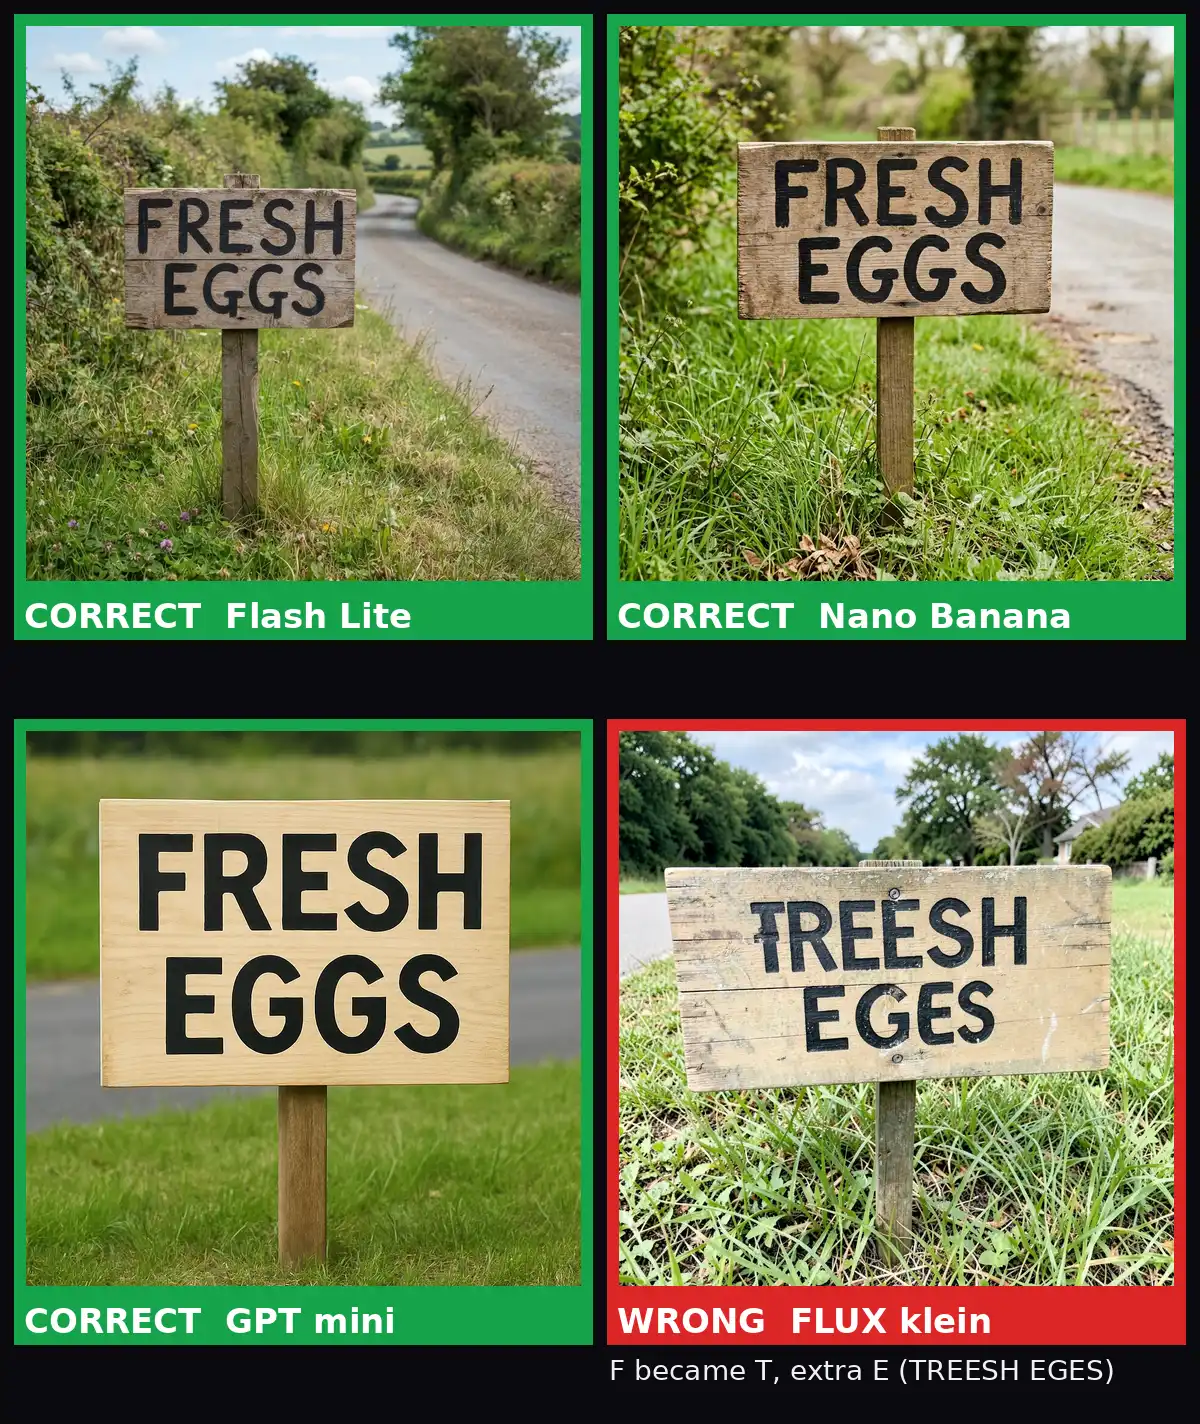
Three of four. Flash Lite, Nano Banana and GPT mini all painted FRESH EGGS cleanly. FLUX klein wrote TREESH EGES: the F became a T and an extra E was added, so it fails even the lenient check.
A short sign in capitals is the easiest job in this set. If your text is one or two words, the three correct models are interchangeable on accuracy and differ on price and speed.
Which model gets a two-line label right?
Three of four. Flash Lite, Nano Banana and GPT mini spelled BLUEBERRY JAM and Batch 24 - Small Farm correctly. FLUX klein garbled BLUEBERRY: the L is lost and the word gains an extra R.
GPT mini broke BLUEBERRY and JAM onto separate lines, so its label has three lines where the prompt asked for two. We did not score line breaks, but a designer who needs an exact layout would.
Which model gets a price list right?
Three of four. Flash Lite, Nano Banana and GPT mini wrote all four items and prices correctly. FLUX klein got 7 of the 10 words and numbers wrong: Esprace, Whiei, ".20" for 3.20, Croviast, Ornage, Juce and 3.55 for 3.50.
A wrong price is the most expensive kind of wrong text. GPT mini wrote "Orange Juice3.50" with no gap before the price. All characters are right, so it passed, but check the spacing if you place the image without editing.
Which model gets four diagram labels right?
Two of four. Flash Lite and Nano Banana drew four boxes in a row, arrows between them, with Upload, Resize, Review and Publish spelled right. FLUX klein drew two boxes labelled "Upioatd" and "Publisw" and left out Resize and Review.
GPT mini spelled the words correctly but drew the row wider than the 1:1 canvas. The first box shows only "load" and the last "Publ". A cut-off label is a failed label, so it is rejected.
Which model gets a UI mock-up right?
Two of four. Nano Banana and GPT mini wrote Sign in, Email, Password and Continue, and nothing else. FLUX klein wrote "Passware" and "Conttnue".
Flash Lite spelled all four words right but added a status bar clock, the placeholder name@example.com and spacing labels such as 24dp and 40dp. The prompt said nothing else may be written, so under strict scoring it is rejected. A reader who does not mind spec annotations may score it differently, which is why the render is shown.
Which model gets a non-English line right?
Three of four. Flash Lite, Nano Banana and GPT mini kept every diacritic of Čerstvý chlieb každý deň: Č, ý, ž and ň. Flash Lite and GPT mini set it in capitals, which we did not score.
FLUX klein kept the caron on Č but dropped the t in Čerstvý, turned chlieb into "chlío" and ended the last two words in wrong glyphs. If the text is not English, test your language before you commit.
Which AI image generator should you pick for text?
- One or two words, a label or a price list: any of the three that passed. On this set GPT mini was the cheapest per correct image ($0.025) but wrapped the P2 label onto three lines; Nano Banana was the most consistent.
- Diagram labels or a UI with nothing extra: Nano Banana, the only model right on both. Flash Lite failed the UI, GPT mini failed the diagram.
- A non-English line: the three passing models kept every diacritic here. One prompt in one language proves little.
- FLUX.2 klein 4B: not for exact text on this evidence. OpenRouter's own one-prompt coffee bag test also caught it writing "SINGLE ORISION".
What does a text-correct image cost?
Billed cost is the usage.cost line OpenRouter returned with each render, not a calculation from the rate card. Listed rates are per million image tokens, from OpenRouter's /models data, so they do not say what one render costs. FLUX klein's model page also prices by megapixel; its 1920 px renders billed $0.017 each.
| Model | Listed, per M tokens | Per render, mean | Range | Spent, 6 renders |
|---|---|---|---|---|
| gemini-3.1-flash-lite-image | $30 | $0.034 | $0.034 | $0.202 |
| gemini-nano-banana-2.1 | $30 | $0.036 | $0.035 to $0.037 | $0.215 |
| flux.2-klein-4b | ~$3.4 | $0.017 | $0.017 | $0.102 |
| gpt-image-1-mini | $8 | $0.021 | $0.0085 to $0.033 | $0.126 |
Cost per text-correct image is the spend on all six renders, failures included, divided by the renders that passed. It is the same under strict and lenient scoring.
| Model | Strict | Lenient | Spent | Per correct |
|---|---|---|---|---|
| gemini-3.1-flash-lite-image | 5/6 | 5/6 | $0.202 | $0.040 |
| gemini-nano-banana-2.1 | 6/6 | 6/6 | $0.215 | $0.036 |
| flux.2-klein-4b | 0/6 | 0/6 | $0.102 | none |
| gpt-image-1-mini | 5/6 | 5/6 | $0.126 | $0.025 |
Full table as CSV, per-render scores as CSV, raw billing lines as CSV.
The cheapest model per render, FLUX klein at $0.017, produced no usable image, so its price per correct image has no number. GPT mini was cheapest per correct image. Its bill swung from $0.0085 on P1, P4 and P5 to about $0.033 on P2, P3 and P6, and we did not find out why. It was also the slowest at 11 to 31 seconds per render, against 2.7 to 5.1 for Flash Lite, 6.6 to 7.5 for Nano Banana and 5.5 to 8.2 for FLUX klein. Total billed for all 24 renders: $0.644.
OpenRouter marks gpt-image-1-mini "going away" on 2026-12-01, so check it before you build on it. OpenRouter's coffee-bag test also covers openai/gpt-image-2, which this test left out.
The cost per usable image article uses the same billing method on a different failure: a bad picture instead of wrong words.
Method and limits
- One render per prompt per model, 24 in all. 5 of 6 against 6 of 6 is a gap of one image. Six more prompts could reverse it. Read it as a spread of text types, not a ranking.
- The strict and lenient rule (every word right; one wrong character allowed) was fixed on the card before the first render. The three scoring-time calls are listed under the first table. One scorer read each render once.
- Three models went through OpenRouter's chat completions endpoint. gpt-image-1-mini went through its
/api/v1/imagesendpoint and its renders carry no generation id. Its first six attempts returned 404, with no charge and no image. - Scoring used the original, unedited renders (1:1, at the API's native size); the images on this page are resized copies, and the grid tiles are all the same size.
- Prompts are in English, plus one Slovak line. One language beyond English says little about others.
Links
- Prices and rates: OpenRouter models, checked 2026-11-18. Peer test: OpenRouter, image generation models compared.
- Related on dataskater: What It Costs to Get One Usable AI Image From an API, the broader best AI image generators of 2026 and the AI Image Generators hub.
What It Costs to Get One Usable AI Image From an API
With six everyday prompts, a usable image cost 0.043 to 0.067 USD on three Gemini image models: between 1.0 and 1.5
 Members
Best AI Image Generators 2026: 8 Tools Compared
Midjourney, ChatGPT, Nano Banana Pro, FLUX.2, Stable Diffusion, Leonardo AI, Adobe Firefly and Ideogram compared, to help you pick a tool for your workflow.